Somebody AI
Image-to-3D avatars rendered in real time in the browser
2025 · CTO & architect · shipped
Real-time photorealistic voice avatars generated from a single image.
Technologies: TypeScript, Three.js, Python, PyTorch, Pipecat, Node.js, React, MongoDB, Docker, Google Cloud
Related expertise: Real-time 3D on the web, AI and LLM, 3D Content Pipeline, Backend & infrastructure, Audio & speech
Overview
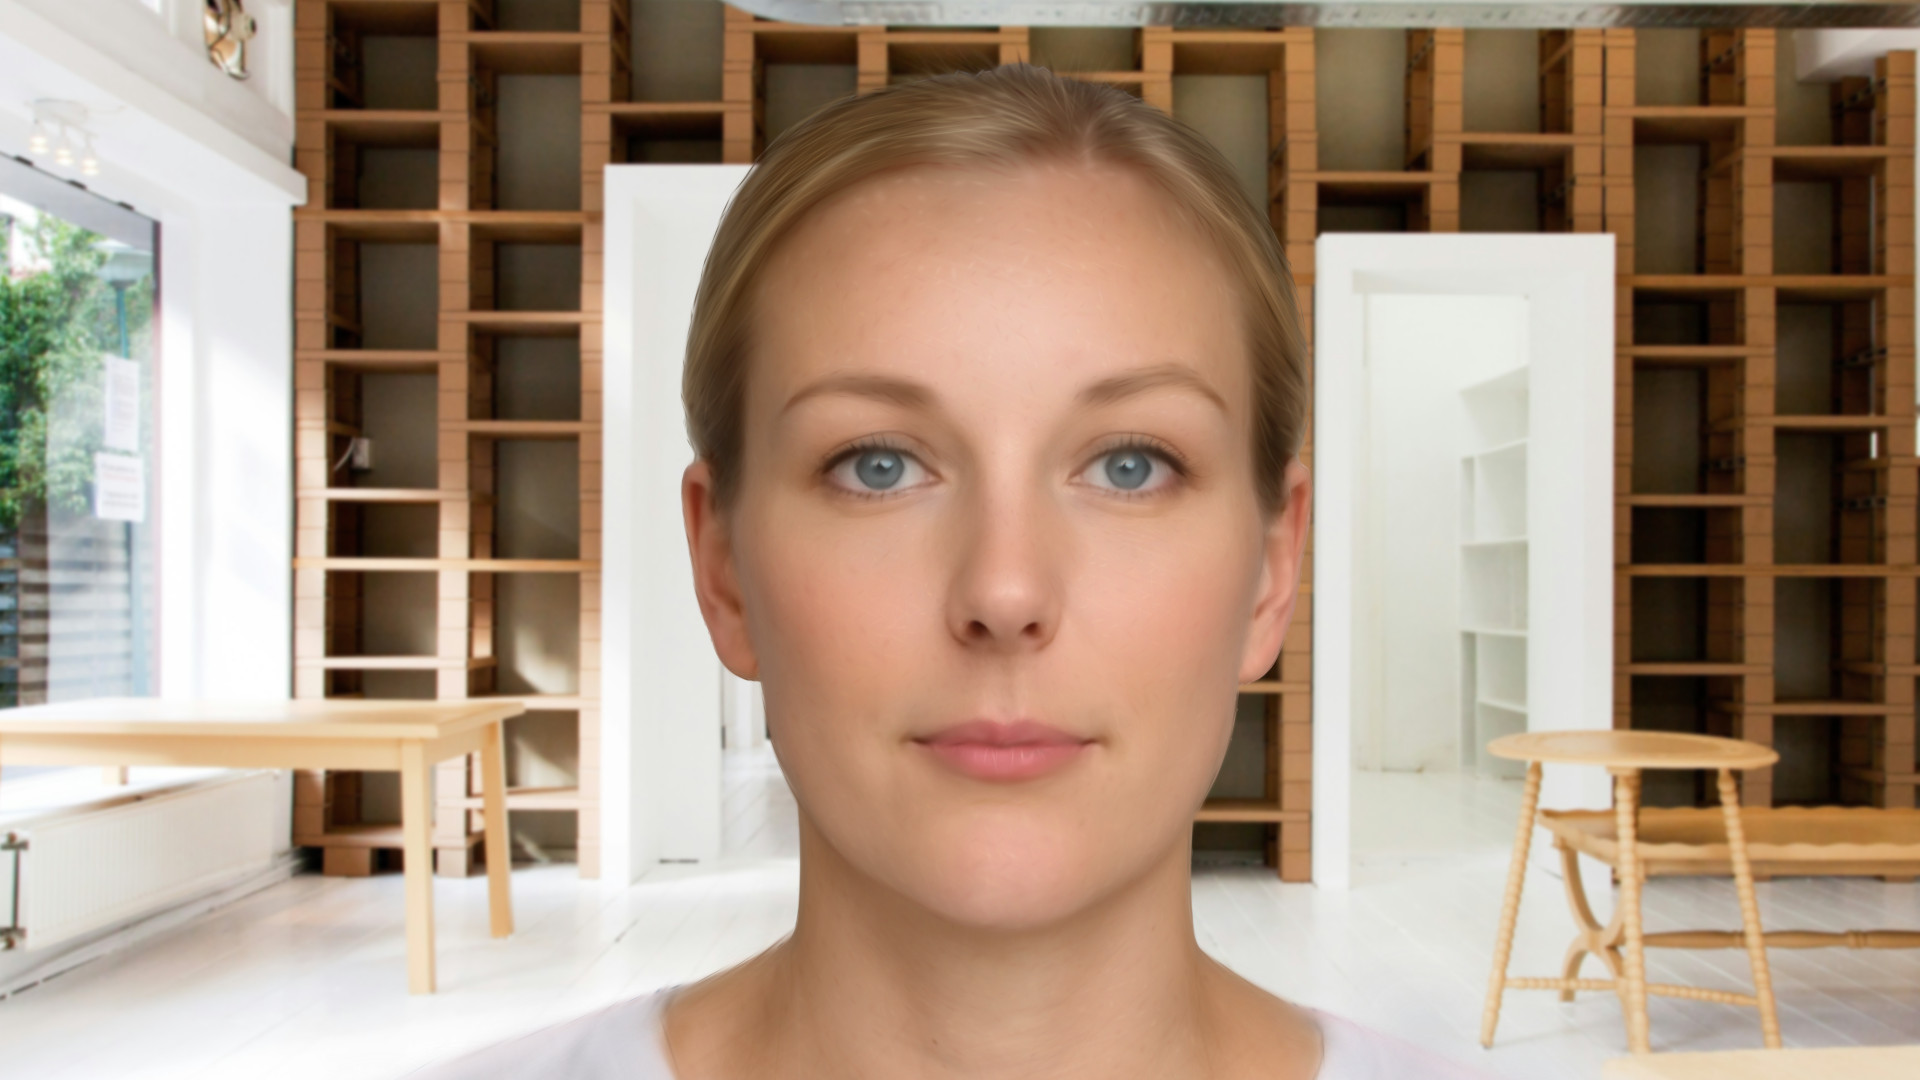
Somebody AI is a platform for conversational AI agents with photorealistic 3D avatars. The avatars are rendered directly in the browser, and users talk to them in real time using their voice.
Clients can define the avatar's appearance, voice and personality, and embed it in any website or product.
Background
Somebody AI started at Hyperspace in 2025. We were creating AI-driven soft-skills training experiences for our platform, and we ended up envisioning a completely new product. More about that in Becoming a CTO.
Companies are using AI agents as support reps, tutors or sales assistants. Real-time AI-generated video is expensive, and the cost grows with every minute of conversation. Our avatars are rendered on the user's device, so there is no video generation cost.
How it works
One photo is enough to make an avatar. A reconstruction pipeline turns it into roughly 20,000 Gaussian splats attached to a FLAME head model, which is what lets the face move. I set that pipeline up and produced every avatar template the product launched with.
The renderer started from published research, and I extended it so the avatars feel alive: the eyes move, the face reacts and the lips follow the speech. Expressions and lip movement come from NVIDIA's Audio2Emotion and Audio2Face, running on the server while the agent talks.
Conversations run on speech-to-speech models through Pipecat, so the product isn't tied to a single AI provider. Clients also get a prompt assistant to help them shape how their agent behaves.
My involvement
- Designed the platform architecture from scratch and led its development.
- Built the agents API, the web app, and the API clients and SDKs for TypeScript and Python.
- Deployed and maintained the avatar generation pipeline.
- Worked on the avatar's expressiveness: eye movement, facial expressions and lipsync.
More about this project, by area: